1
Set an absolute threshold
Alert on remaining free space (for example, under 15% free) rather than only on percentage used, this reads more intuitively during an incident.
2
Also alert on growth rate
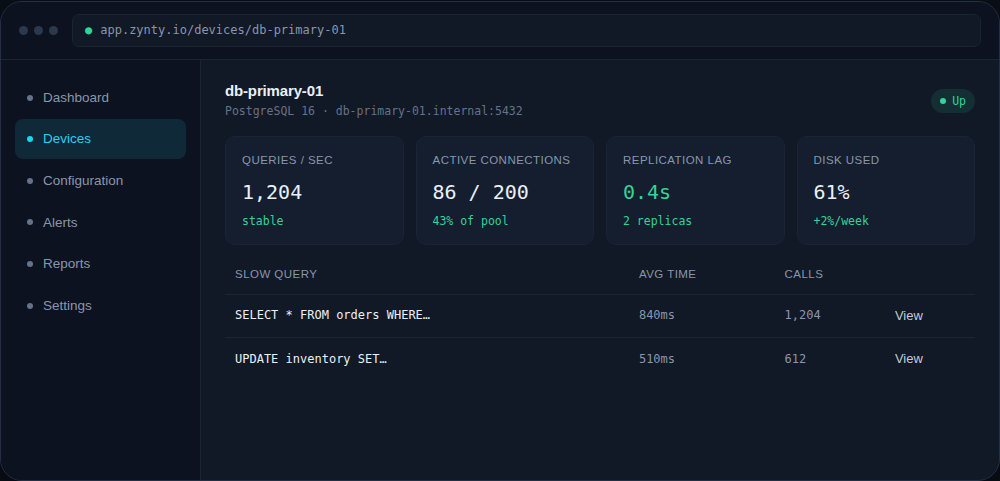
A sudden jump in daily growth, even well under the absolute threshold, often catches a problem (like a missing index causing table bloat) days before it becomes urgent.
1
3
Give yourself lead time
Disk-full database incidents are some of the most disruptive to recover from cleanly, size the alert threshold around how long it actually takes your team to provision more space, not just when the situation becomes visible.